Typical configuration
4 GPU AI Server
- chassis
- ASUS ESC4000A-E12 (2U)
- cpu
- Single AMD EPYC 9005
- gpu
- 4× NVIDIA H200 NVL or RTX PRO 6000 Blackwell (PCIe)
- ram
- 512GB DDR5 ECC
- storage
- NVMe U.2 / U.3
 Spend over €5,500 and receive a free €100 Amazon gift voucher
Enterprise rack servers
Built for AI training, inference and high-performance compute.
GPU rack servers tuned for multi-accelerator training and inference. PCIe lane budget and NVMe scratch staging reduce GPU wait time; power and cooling sustain utilisation.
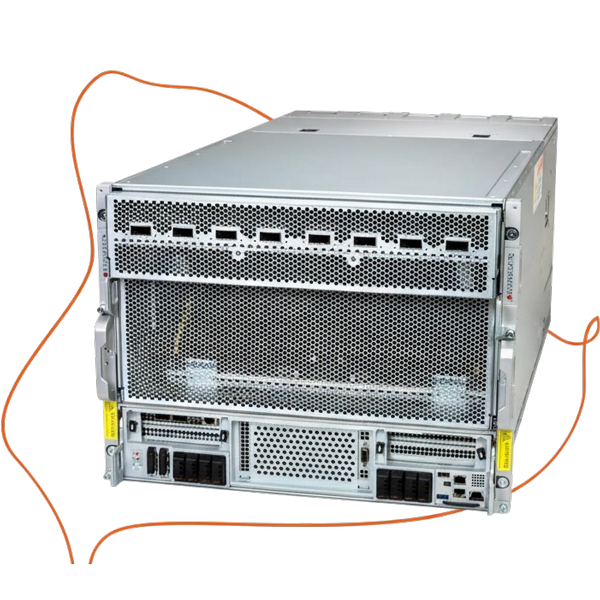
Experts in configuring GPU Rack Servers
GPU chassis range from 1U and 2U nodes with one to four GPUs, through 4U and 5U systems with eight to ten PCIe GPUs, to a 10U NVIDIA HGX B200 platform.
Each card connects to the host over PCIe 5.0; chassis with ten or more GPUs use PCIe switches to share CPU lanes between cards.
Single- and dual-socket EPYC or Xeon hosts supply the cores and memory channels that data loaders and preprocessing need alongside the GPUs.
Every GPU chassis is offered with redundant power supply options rated for its maximum GPU configuration.
Local NVMe holds datasets and checkpoints next to the GPUs, cutting reliance on shared network storage.
Cuts step time by keeping multi-GPU training compute-bound during ingestion and gradient exchange.
Improves inference throughput with low-latency batch scheduling across nodes.
Reduces render latency by sustaining GPU pipeline saturation for VFX and 3D workloads.
Improves parallel job throughput by keeping accelerator memory and I/O paths fed during long runs.
Our team will spec the right platform for your workload, validate compatibility, and turn it around fast.
PCIe and SXM options
Double-width PCIe 5.0 GPU slots on most chassis, with eight NVIDIA HGX B200 SXM GPUs on NVSwitch for all-to-all bandwidth on the largest platform.
Host CPU and memory
AMD EPYC or Intel Xeon with DDR5 ECC. NVIDIA's DGX systems pair roughly 1.5 to 3 times as much system RAM as GPU memory, a sensible starting point for training.
Power delivery
Redundant PSUs on 200–240V feeds. A fully loaded 8-GPU node can draw several kilowatts, and HGX B200 systems over 10kW.
Airflow
Front-to-back cooling with high-static-pressure fans, built for accelerators that have no fans of their own.
Representative configurations — every build is tailored to your workload and environment.
Typical configuration
Typical configuration
2-GPU nodes for inference and small training runs with stable thermals.
4-GPU systems that balance PCIe expansion, power, and sustained throughput.
8-GPU chassis sized for dense deployments and sustained utilisation.
Instant Quotes
Configure and price in minutes
Guaranteed Compatible
If it's listed, it works together
Pre-Built & Tested
Full burn-in before it leaves us
UK Headquarters
Built, tested, and shipped from the UK
Share your workload requirements; we spec, validate, and quote to deployment constraints.